Quantization: fewer bits per weight
Quantization represents weights or activations with fewer possible values. Instead of preserving every float32 weight, a model can store a small integer code and enough information to interpret it.
A smaller set of values
One simple scheme maps a weight tensor’s minimum to code 0 and its maximum to 255. Intermediate weights are rounded to nearby codes. The scale records the distance between adjacent reconstructed values.
Eight-bit codes need about a quarter of the raw space of float32 weights, plus metadata. Four-bit codes offer 16 possible values. Fewer levels make the approximation coarser; a wide range caused by outliers can leave many ordinary weights poorly represented. Grouping weights and giving each group its own scale can improve the fit.
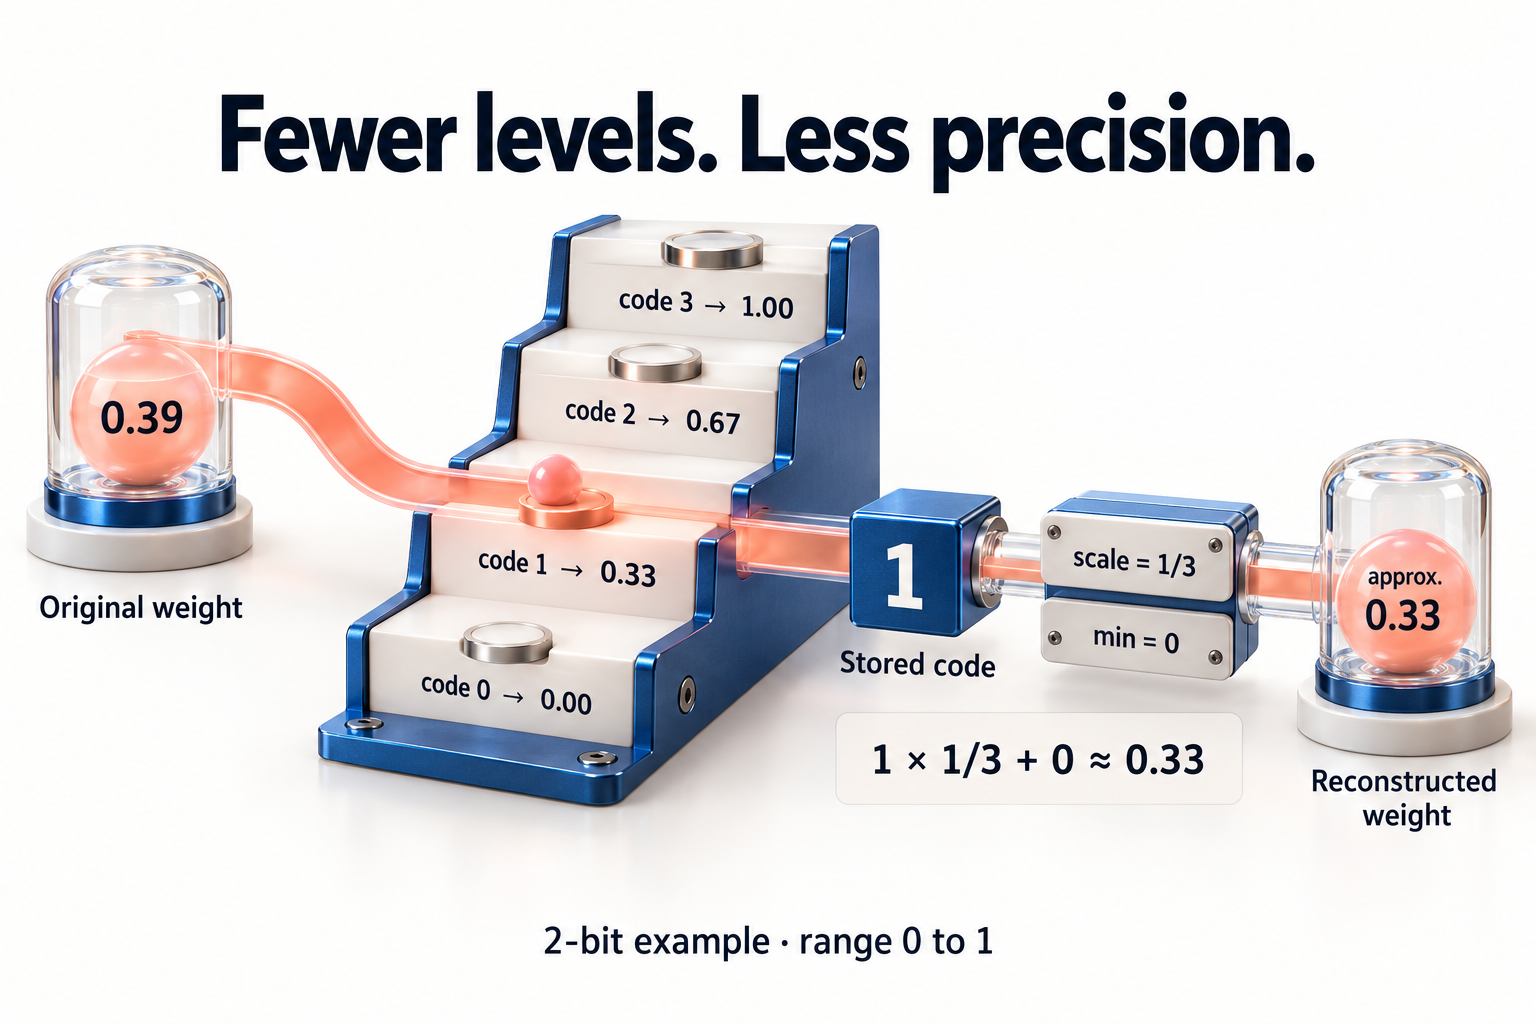
The illustration uses two bits; the code below uses eight.
Pack, then reconstruct
This NumPy code follows the download-packing mechanism used by our browser model:
import numpy as np


def pack_weights(weights):
    minimum = float(weights.min())
    scale = float(weights.max() - minimum) / 255 or 1.0
    codes = np.clip(np.rint((weights - minimum) / scale), 0, 255)
    return codes.astype(np.uint8), minimum, scale


def unpack_weights(codes, minimum, scale):
    return codes.astype(np.float32) * scale + minimum
Pass a model weight array to pack_weights, store the returned codes and two scalars, then use unpack_weights to reconstruct an approximate float32 tensor. Rounding loses information, so the reconstructed values need not exactly match the originals.
Storage and execution are different choices
A runtime may reconstruct float weights before calculation, or use kernels that operate on quantized data. The first approach saves download space while restoring the original float weight footprint in memory. The second can also reduce runtime memory and computation when the hardware and implementation support it.
Quantization-aware training and calibration can help preserve useful behaviour. Judge the result on actual model tasks as well as reconstruction error: a smaller weight file alone does not establish unchanged quality or faster generation.
Related: parameters and weights, KV cache, our quantized browser model.