Prompt caching: reuse the beginning of a request
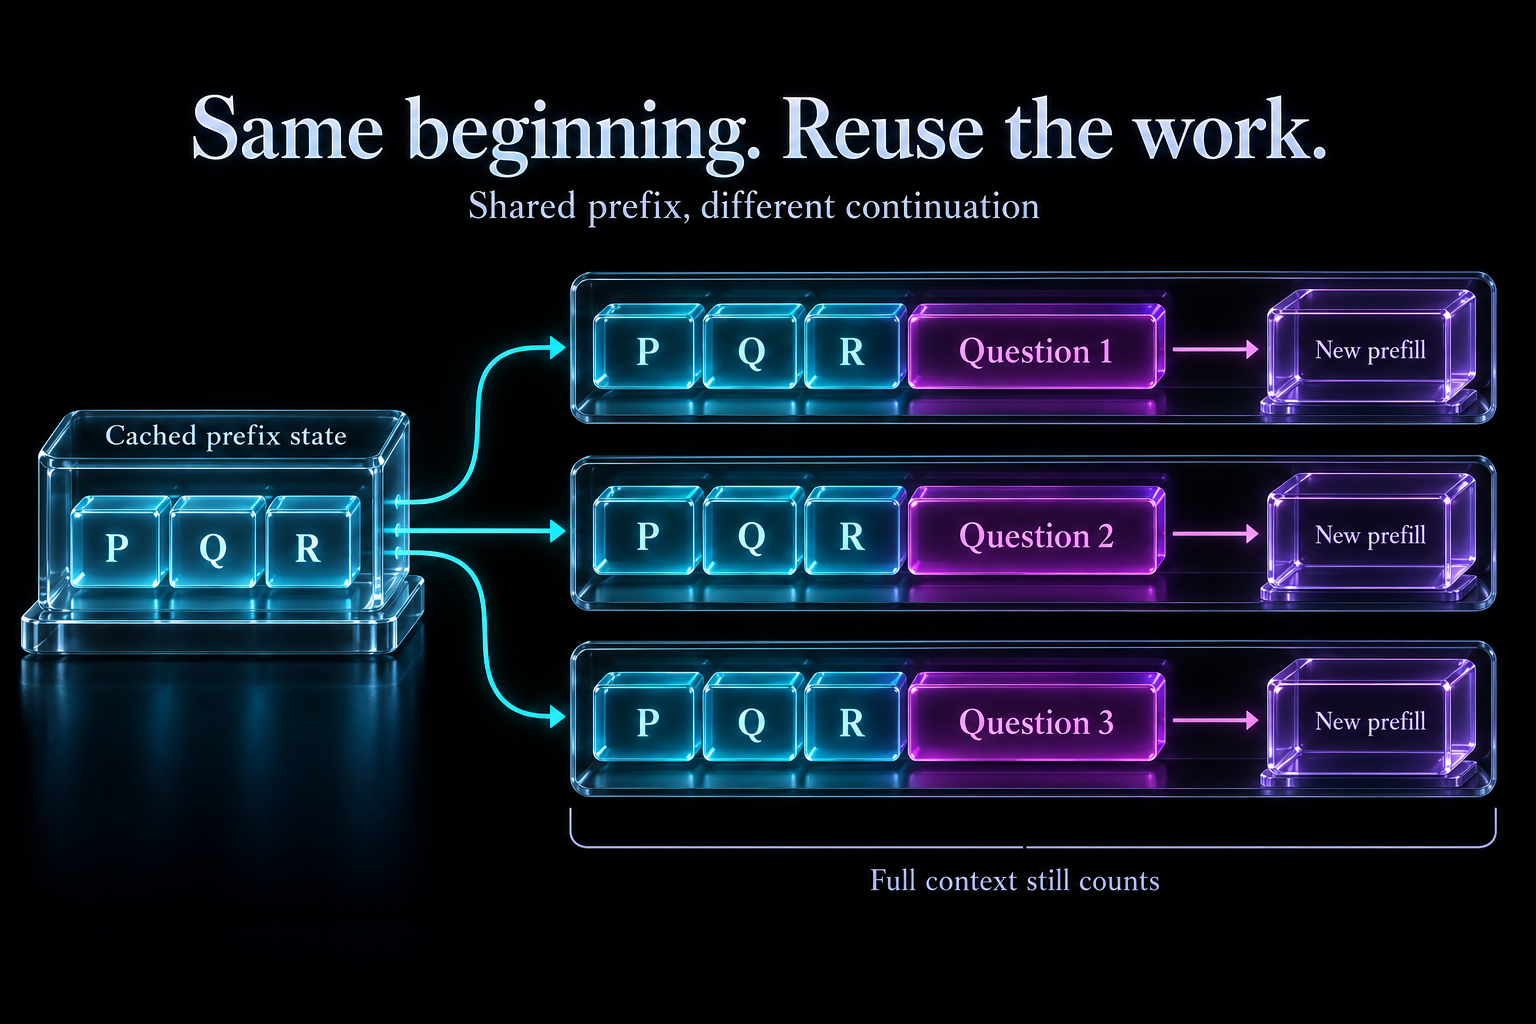
Prompt caching reuses computation for input that matches an earlier request. For a causal Transformer, the keys and values for an unchanged prefix remain valid when new tokens are appended. Reusing that KV state avoids processing the same beginning again.
This differs from caching a finished answer. The model still generates a new continuation, conditioned on the full current request. A repeated document can supply shared context for many different questions.
Why the prefix matters
The state for a token depends on the tokens before it. Put stable instructions and reference material first, then append the changing question. If the beginning changes, later text can be identical yet require different cached state.
Serving systems can identify reusable blocks from token IDs and preceding blocks. Model configuration, adapters and non-text inputs can also affect whether state is reusable. The useful condition is a matching computation, rather than merely similar meaning.
Reuse has a lifetime
Keeping state available consumes memory or storage. Providers and serving engines therefore manage retention, eviction and isolation. API pricing and retention rules vary; a cheap cached-input rate is not a guarantee that a prefix remains available forever.
A cache hit reduces new prefill work. It does not eliminate the attention work needed to use the prefix during generation, and cached tokens still occupy the context window.
The practical pattern is simple: keep reusable content stable, put request-specific content after it, and inspect reported cache usage rather than assuming every repeated request was a hit.